Research & Publications
Selected First-Author Papers
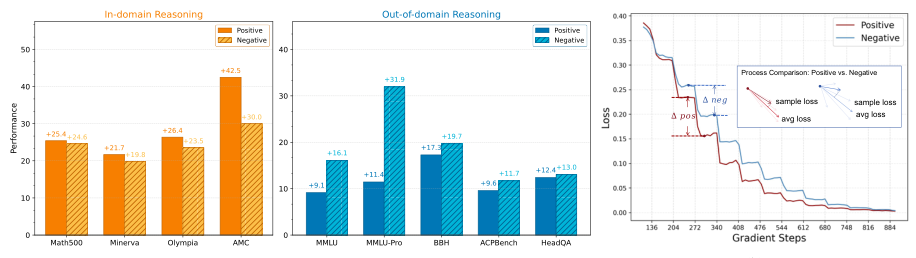
Learning from Mistakes: Negative Reasoning Samples Enhance Out-of-Domain Generalization
Negative reasoning samples improve out-of-domain generalization; GLOW adaptively reweights training examples using their learning dynamics.
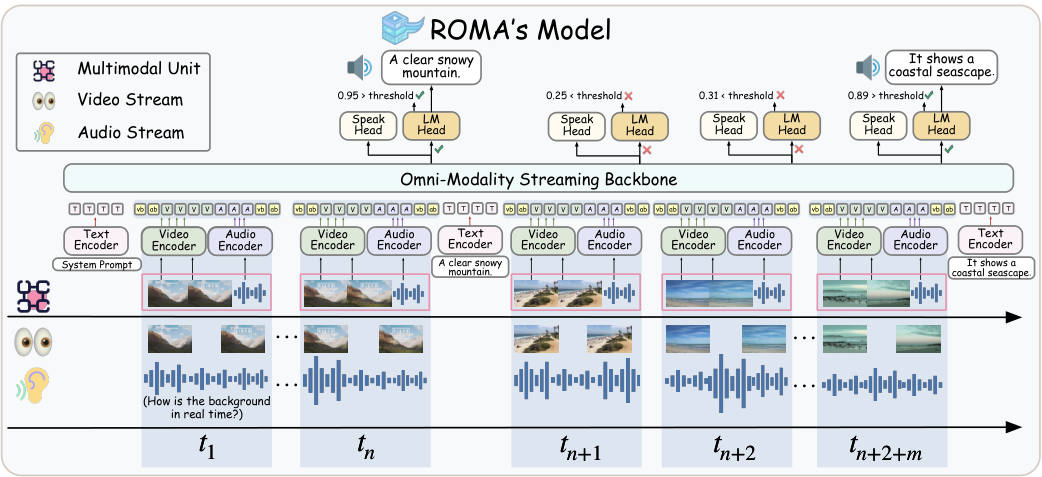
ROMA: Real-time Omni-Multimodal Assistant with Interactive Streaming Understanding
A real-time omni-multimodal assistant that supports proactive alerts, live narration, and reactive question answering over audio-video streams.
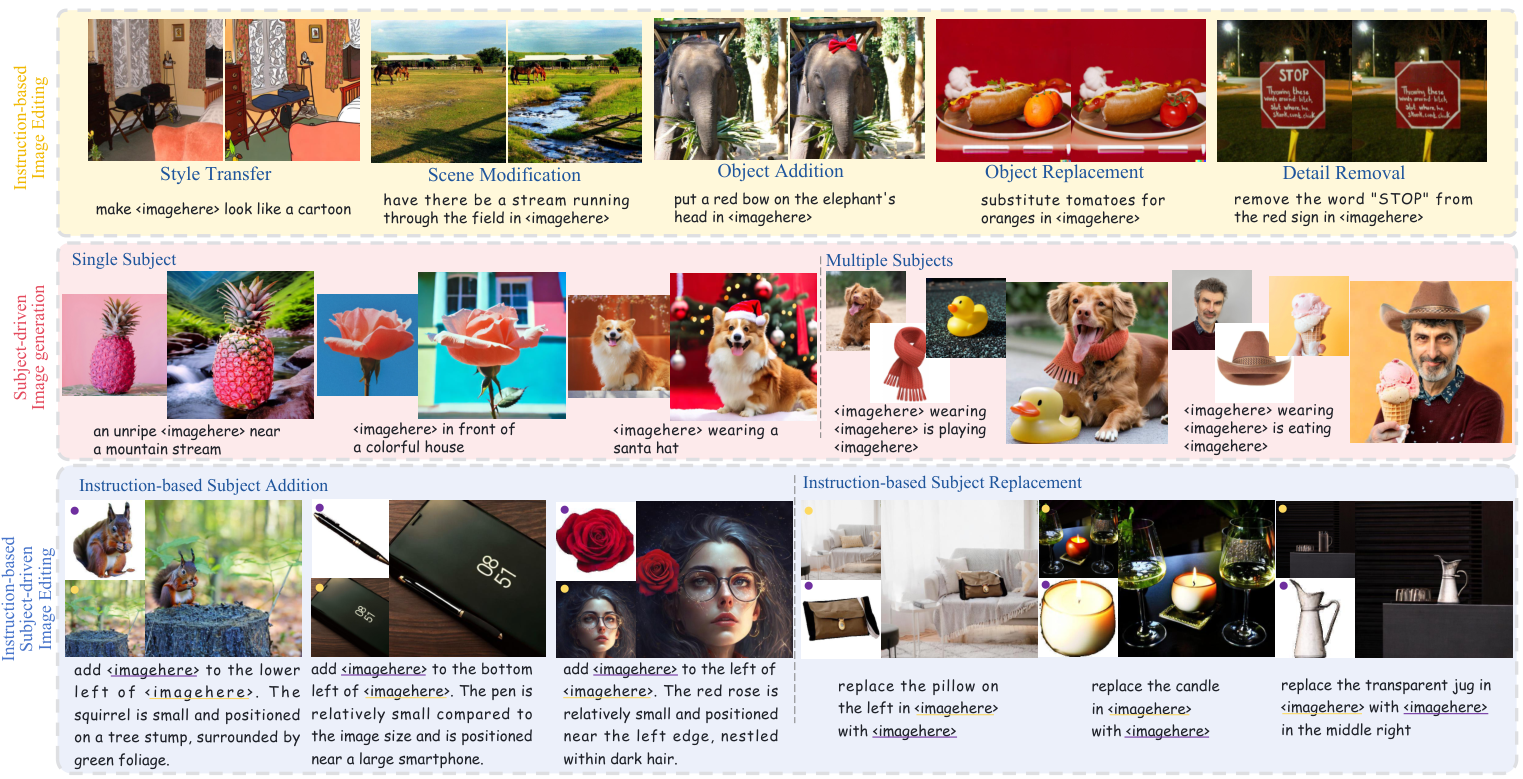
MIGE: Mutually Enhanced Multimodal Instruction-Based Image Generation and Editing
A unified framework for subject-driven generation and instruction-based image editing, with transfer to compositional editing tasks.
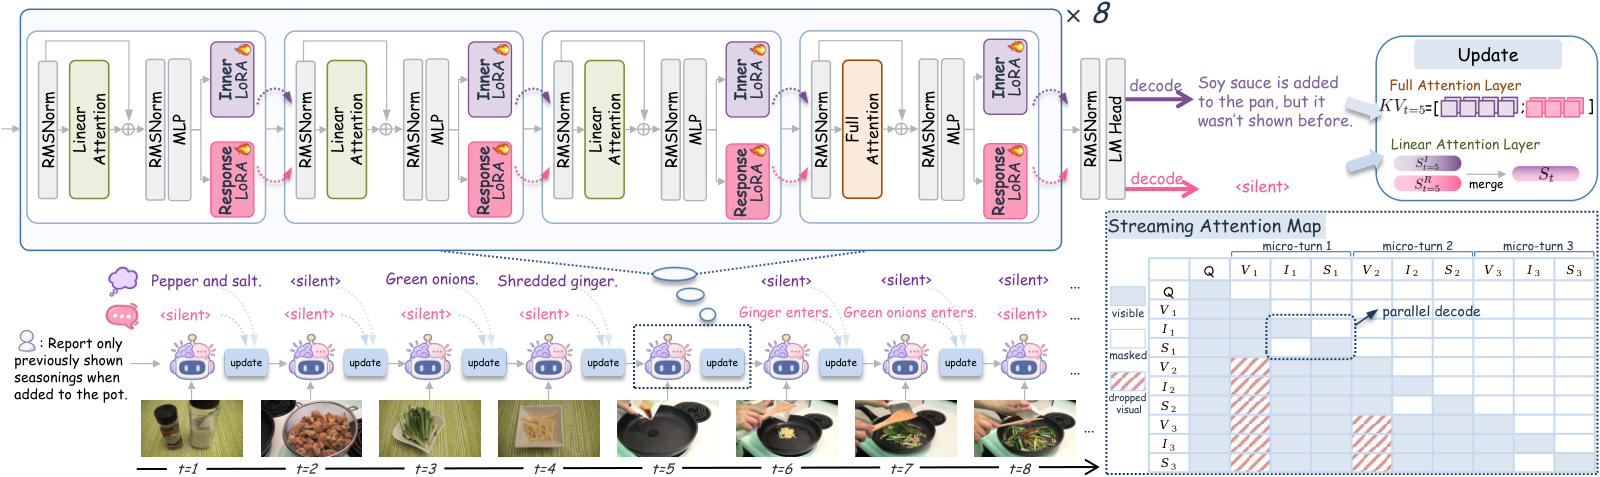
SyncPro: Synchronous Reasoning and Responding for Proactive Streaming Video Understanding
Proactive streaming video understanding with synchronized thinking and response streams, trained with supervised fine-tuning and reinforcement learning.
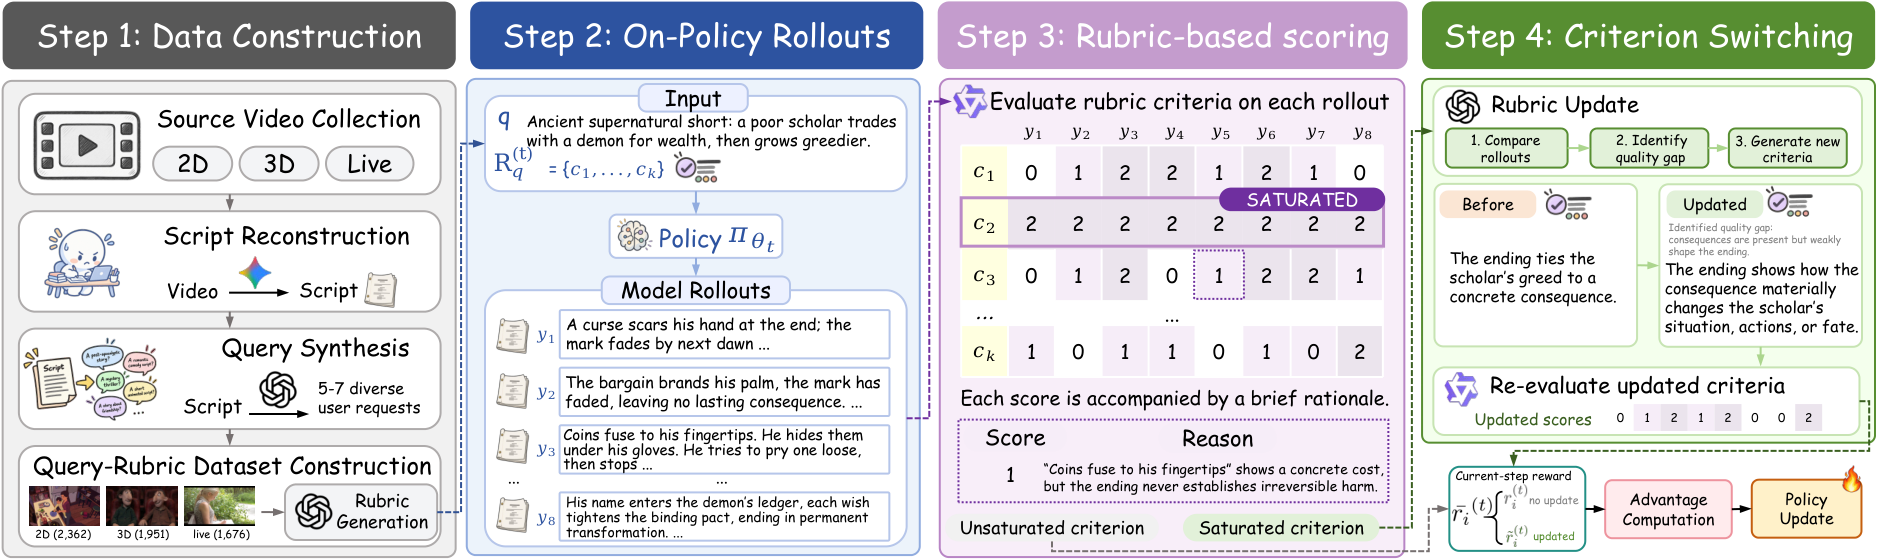
RARE: Reinforcement Learning with Adaptive Rubric Evolution for Open-Ended Generation
Adaptive rubric evolution for open-ended generation, using current policy feedback to replace saturated criteria while retaining other criteria and scores.
Collaborative Work
AVA-Encoder: Towards Agent-Native Video Representation Learning
Agent-native video representations that connect film understanding, structured knowledge, and video reconstruction.
DiffImaginE: Imagine to Verify Entity Types with Diffusion
Type-conditioned diffusion for verifying entity types using multimodal evidence.
Chain-of-Memory: Lightweight Memory Construction with Dynamic Evolution for LLM Agents
Lightweight memory construction and dynamic memory-chain evolution for long-term reasoning in LLM agents.
Beyond Entangled Planning: Task-Decoupled Planning for Long-Horizon Agents
Task-decoupled planning with global supervision for long-horizon agents.
Towards Robust Process Reward Modeling via Noise-aware Learning
Noise-aware learning and reflection-aware label correction for more robust process reward models.
GIFT: Games as Informal Training for Generalizable LLMs
Game-based informal learning and coordinated subtask training to improve LLM generalization.
Robix: A Unified Model for Robot Interaction, Reasoning and Planning
A unified high-level robot model for language interaction, reasoning, and long-horizon task planning.